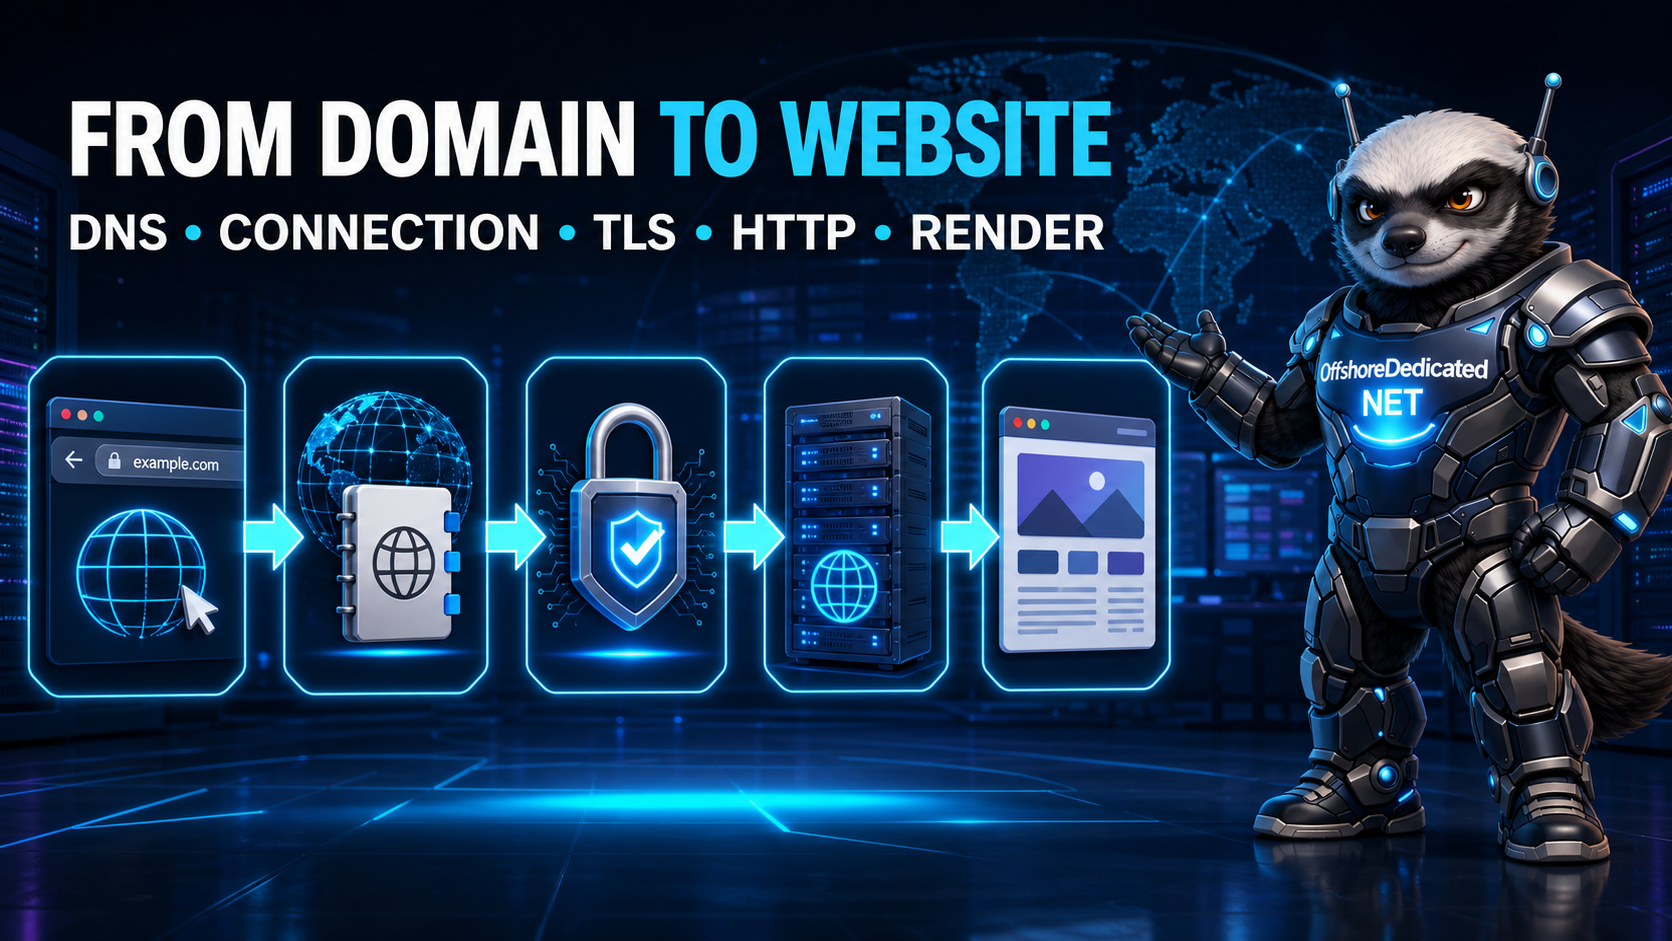

Typing a domain name into a browser feels almost instantaneous. You enter an address, press Enter, and a website appears.
Behind that simple action, the browser may need to find an IP address, establish a network connection, verify a security certificate, request files from a server, and convert those files into the page displayed on your screen.
Some stages may be skipped or accelerated through caching, and modern protocols can combine parts of the process. However, the basic journey remains the same.
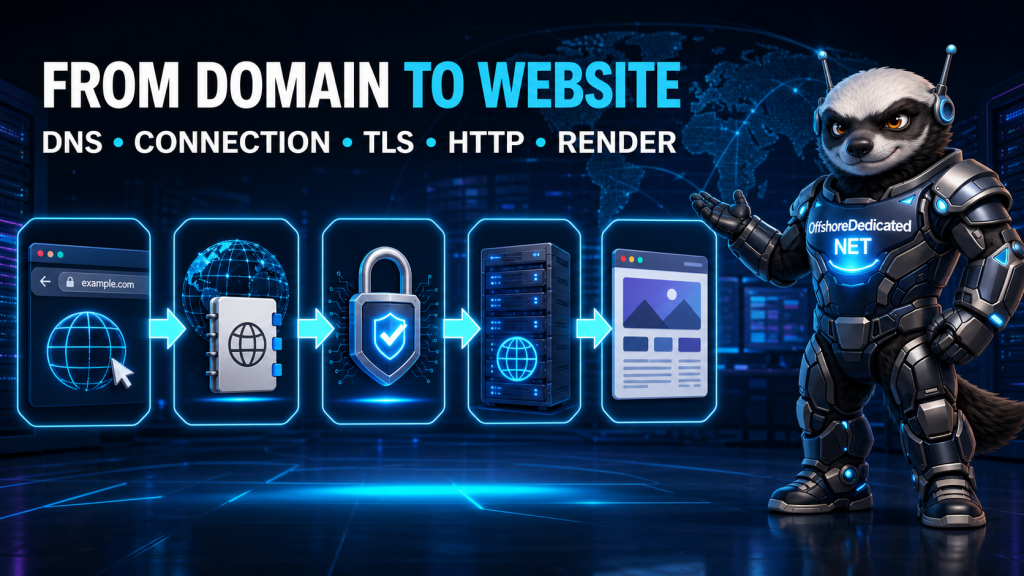
Let us follow a request from the address bar to the finished website.
Step 1: The Browser Interprets What You Entered
Suppose you enter:
https://example.com/productsThis is a URL, or Uniform Resource Locator. It contains several pieces of information:
httpsspecifies the protocol.example.comis the domain name./productsis the requested path.
If you enter only example.com, the browser will normally infer that you want to visit a website and choose HTTP or HTTPS. Browser behavior, saved history, security policies, and search settings can influence this decision.
The browser may first check whether it already knows something about the destination. It can consult:
- Its DNS cache
- Its HTTP cache
- A service worker
- Previously established network connections
- HTTP Strict Transport Security information
- Previously stored redirects
A repeat visit may therefore require fewer steps than a first visit.
Step 2: DNS Finds the Server’s IP Address
Networks communicate using IP addresses rather than human-friendly domain names. The Domain Name System, or DNS, connects the two.
The browser and operating system first check local caches. If no usable answer is available, the request is sent to a recursive DNS resolver. That resolver may be operated by an internet service provider, organization, public DNS provider, or privacy-focused encrypted DNS service.
If the resolver also lacks a cached answer, it follows the DNS hierarchy.
A Simplified DNS Lookup
For example.com, the resolver may contact:
- A root nameserver
- A
.comtop-level domain nameserver - The authoritative nameserver for
example.com
The authoritative nameserver returns the appropriate DNS record. Common results include:
- An
Arecord containing an IPv4 address - An
AAAArecord containing an IPv6 address - A
CNAMEpointing to another hostname
The answer includes a Time to Live, or TTL, which indicates how long it may be cached.
DNS does not normally send the website itself. It helps the client discover where the relevant service can be reached.
You can inspect DNS records from Linux, macOS, or another system with dig installed:
dig example.comRequest only IPv4 address records:
dig example.com ACheck IPv6 records:
dig example.com AAAADNS problems can prevent a perfectly healthy server from being reached. Incorrect records, unavailable nameservers, stale caches, and expired domains can all interrupt this stage.
Step 3: Traffic Travels Toward the Destination
Once an IP address is known, the device sends packets toward that destination.
The packets usually pass through:
- The local network
- A router or gateway
- The internet service provider
- Multiple intermediate networks
- The destination network or a nearby CDN location
Routers do not need to understand the web page. They examine addressing information and move packets toward the next appropriate network.
The exact route can change according to internet routing decisions, network congestion, failures, peering relationships, and whether a content delivery network is involved.
You can view an approximate network path with:
traceroute example.comOn systems where the command is named tracepath:
tracepath example.comSome routers do not answer diagnostic probes, so missing hops do not necessarily indicate broken connectivity.
Step 4: The Browser Establishes a Connection
After reaching the destination network, the browser must establish a usable connection.
For HTTP/1.1 or HTTP/2 over HTTPS, this normally begins with a TCP connection. TCP uses a three-step handshake commonly summarized as:
SYN → SYN-ACK → ACKThis process confirms that the client and server can communicate and establishes the state needed for reliable data transfer.
Modern browsers may reuse an existing connection rather than creating a new one. Reusing connections reduces delay when multiple resources come from the same origin.
HTTP/3 works differently. It uses QUIC over UDP and integrates secure transport establishment more tightly. The visible result is still an HTTP request and response, but the underlying connection is not the traditional TCP-plus-TLS sequence.
Step 5: TLS Secures the HTTPS Connection
Most websites use HTTPS. The S indicates that HTTP traffic is protected using Transport Layer Security, or TLS.
During TLS negotiation, the browser and server:
- Agree on supported cryptographic parameters
- Establish encryption keys
- Receive and verify the server’s certificate
- Confirm that the certificate matches the requested hostname
- Create an encrypted communication channel
The browser verifies whether the certificate chains back to a trusted certificate authority and whether it is currently valid.
A valid certificate helps the browser confirm that it has reached a server authorized for that domain. Encryption then protects the traffic from casual reading or modification while it travels across the network.
TLS does not prove that the website itself is honest, malware-free, or trustworthy. It protects the connection and authenticates the domain according to the certificate system.
The MDN explanation of TLS provides more detail about certificates, encryption, HTTPS and HSTS.
Step 6: The Browser Sends an HTTP Request
With the connection ready, the browser sends an HTTP request.
A simplified request might resemble:
Method: GET
Path: /products
Host: example.com
Accept: text/html
Real requests usually contain additional headers. These may describe accepted content formats, compression support, language preferences, cached versions, cookies, and other browser information.
The request specifies:
- The HTTP method
- The requested path
- The hostname
- Relevant headers
- Sometimes a request body
A normal page visit commonly uses GET. A form submission or API operation may use POST, PUT, PATCH, or another method.
Cookies may be included if the browser previously stored them and their domain, path, expiry, and security rules permit transmission.
Step 7: The Request Reaches the Hosting Infrastructure
The IP address may lead directly to a web server, but modern websites often place other systems in front of the application.
The request might first encounter:
- A content delivery network
- A DDoS protection service
- A firewall
- A reverse proxy
- A load balancer
- A caching layer
- A web application firewall
These systems can filter harmful traffic, terminate TLS, serve cached content, or direct the request to an available backend server.
A small site on offshore shared web hosting may share underlying resources with other accounts. A VPS-hosted website or application receives its own virtualized server environment. Larger or more dynamic deployments may use flexible cloud-server infrastructure.
The browser-facing process is broadly similar, even though the infrastructure behind the domain may be very different.
Our complete web-hosting infrastructure guide explains the hardware, virtualization, operating system, storage, network, and application layers in greater detail.
Step 8: The Server Processes the Request
The web server examines the hostname, path, method, and other request details.
For a static page, software such as NGINX or Apache may read an HTML file from storage and return it directly.
A dynamic site requires more work. The request may be passed to:
- PHP
- Node.js
- Python
- Ruby
- Java
- Another application runtime
The application may then:
- Check the user’s session
- Validate permissions
- Query a database
- Read or update cached data
- Generate HTML or JSON
- Return the result to the web server
A content management system might retrieve the page title, body, navigation menu, user state, and recent posts from several data sources before constructing the response.
Hosting control panels help administrators configure many of these layers. Our guide to hosting control panels and their architecture explains how panels coordinate web servers, DNS, databases, certificates and other services.
Step 9: The Server Returns an HTTP Response
The server sends an HTTP response containing a status code, headers, and usually a response body.
A simplified response looks like:
HTTP/1.1 200 OK
Content-Type: text/html; charset=UTF-8
Cache-Control: public, max-age=300
Content-Encoding: gzip
The response body then contains the HTML document.
Common status codes include:
200 OK— the request succeeded301 Moved Permanently— the resource has a permanent new location302 Found— the resource is temporarily available elsewhere403 Forbidden— the server understood but refused the request404 Not Found— the requested resource was not found500 Internal Server Error— server-side processing failed503 Service Unavailable— the service is temporarily unable to respond
A redirect causes the browser to make another request to the location supplied by the server.
Inspect response headers with:
curl -I https://example.comFollow redirects as well:
curl -IL https://example.comStep 10: The Browser Parses the HTML
Receiving HTML does not complete the page.
The browser parses the HTML and builds the Document Object Model, commonly called the DOM. The DOM represents the document as a tree of elements, text, attributes, and relationships.
While reading the HTML, the browser discovers references to other resources, including:
- CSS stylesheets
- JavaScript files
- Images
- Fonts
- Videos
- API endpoints
It sends additional HTTP requests for the resources that are not already available from a valid cache.
Those files may use different hostnames, which can require additional DNS lookups and connections.
Step 11: CSS, Layout and Painting Create the Page
The browser parses CSS and builds a CSS Object Model, or CSSOM. It combines applicable style information with visible document elements to create a render tree.
It then performs several visual steps:
- Style calculation determines which CSS rules apply.
- Layout calculates the size and position of visible elements.
- Paint draws text, colors, borders, images and other details.
- Compositing combines visual layers into the final result.
JavaScript can alter the DOM and styles, request more data, respond to user actions, and trigger additional rendering work.
The process is explained more deeply in MDN’s guide to how browsers load and render websites.
A page can appear on screen before every image, script, or secondary resource has finished downloading. Browsers try to display useful content as early as possible.
Why Some Websites Load Faster Than Others
Every stage can introduce delay.
Performance may be affected by:
- Slow DNS resolution
- Long physical distance
- Inefficient network routing
- Packet loss
- Repeated connection setup
- Slow TLS negotiation
- Overloaded server resources
- Uncached database queries
- Large images
- Excessive JavaScript
- Too many third-party resources
- Poor cache configuration
- Slow external APIs
A fast server cannot completely compensate for a badly designed page. Likewise, an optimized frontend may still feel slow when the application or database takes several seconds to respond.
How to Watch the Process Yourself
Modern browsers include developer tools.
Open the Network panel, reload a page, and inspect:
- Requested resources
- Status codes
- Response headers
- File sizes
- Request timing
- Connection details
- Cache usage
- Redirects
- Failed requests
You can also combine several command-line checks:
dig example.com
curl -IL https://example.com
traceroute example.com
These commands do not reveal everything happening inside the browser or infrastructure, but they help separate DNS, routing, TLS and HTTP problems.
Final Thoughts
When you type a domain into a browser, the browser does far more than download one file.
It interprets the address, resolves the domain through DNS, reaches the destination network, establishes a connection, negotiates TLS, sends an HTTP request, receives the server’s response, downloads supporting resources, and turns HTML, CSS and JavaScript into visible pixels.
Caches, CDNs, reused connections and modern protocols may shorten or rearrange parts of the journey. The underlying goal remains unchanged: locate the correct service, communicate securely, retrieve the required resources, and present them as an interactive website.
What feels like a single click is really a carefully coordinated conversation between the browser, DNS infrastructure, networks, hosting systems, application software and web standards.